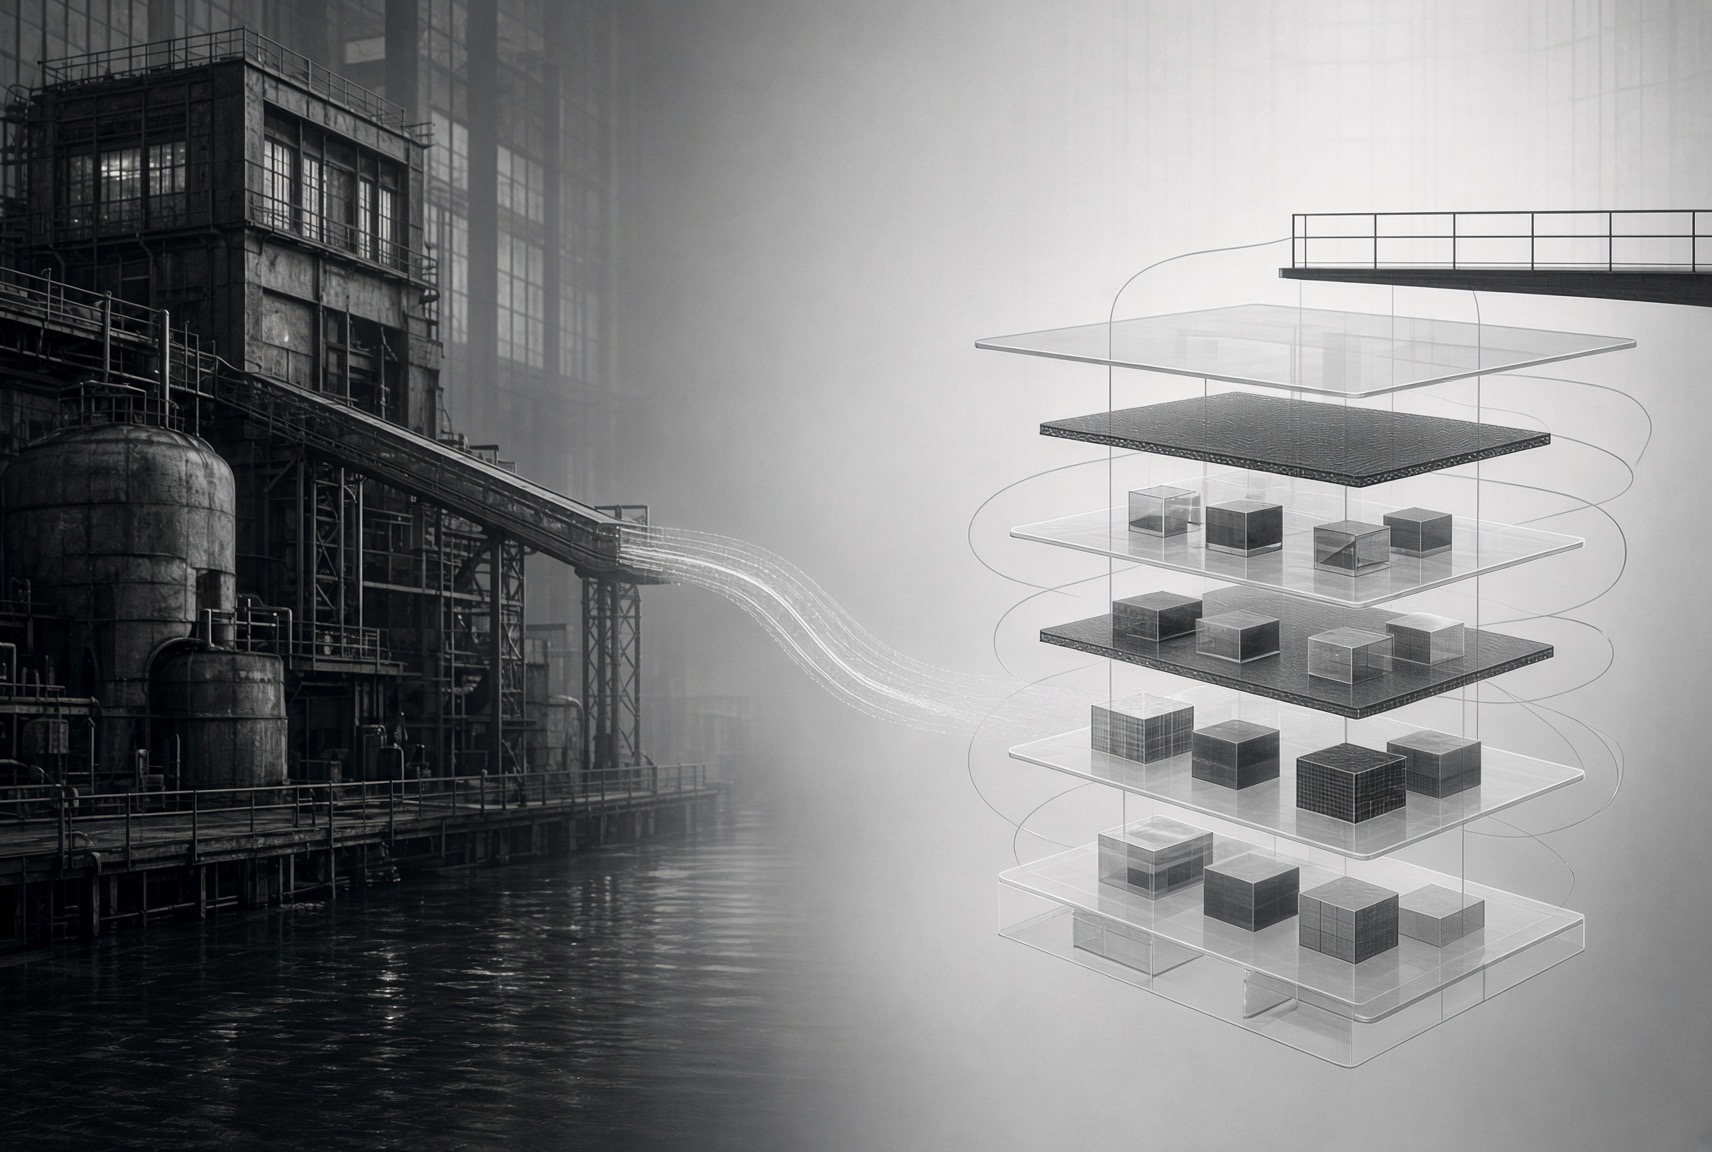
AI-native does not mean speeding up existing workflows with tools. It means redesigning how work is done: intelligence layers run the chain, humans stay above the loop and decide at the gates.
McKinsey describes this for software as a fundamental reversal: AI is not a plug-in but the starting point of the architecture. Modules are loosely coupled, models run as microservices and can be replaced without destabilizing the system.
Bain makes the same demand for banks: do not layer tools on top of the existing model; rebuild agentic experiences, autonomous workflows, and a modern stack from the ground up. The ambition is clear—tenfold productivity, a hundredfold increase in experimentation speed, and 90 percent shorter time-to-market.
Previous pieces on evolut make the same point: the company cannot become AI-native from the inside. You build an edge twin, independent of the mothership, prove it on real workflows, and migrate once the numbers force the decision.
Why single-vendor dependency is risky
MUFG took the other path. The bank works closely with OpenAI, is rolling out ChatGPT Enterprise to roughly 35,000 employees, building custom GPTs, and investing in training and culture. The reported effects- 20–30 percent less effort on selected tasks, more than 1,800 custom GPTs in four months- are real. At the same time, the organization is aligning systems, processes, and daily work to a single provider’s capabilities and ecosystem.
This creates dependencies beyond the model itself. Prices and limits can change. Models get deprecated or restricted. The real costs often sit in everything built around the model: context and memory, integrations into internal systems, evaluation suites, guardrails, and the rules that determine what an agent can do.
Even if you can technically switch the model, the organizational and compliance cost of the switch becomes high and slow once those surrounding layers are tied to one vendor’s formats and interfaces.
In regulated industries, this is sharper. Audit trails, data residency, and the ability to demonstrate compliance must travel with you. A single provider then controls not only inference but the company’s freedom of movement.
How to stay flexible: keep models interchangeable
The alternative is modularity from the start. McKinsey calls this the “model-as-a-microservice” pattern, with versioned interfaces and retrain-and-replace pipelines. You design so that components remain swappable—“design for the swap.” A thin governance layer connects best-of-breed components and keeps them interchangeable instead of building a monolithic platform.
In practice, this means:
- Your own data and context layer, not bound to one vendor’s format
- Evaluations and guardrails that belong to the company and run independently of any model
- Routing by task: the cheapest model for routine work, the strongest for complex steps, local or specialized models where needed
- A clear separation between deterministic rules and probabilistic inference
The edge twin is where you build and prove this. It stays inside the firewall, reports to the CEO, and runs in parallel with the core. There you test different models against the same inputs, measure cycle time, quality, cost, and risk, and decide on the numbers.
Humans remain at every material gate. The intelligence layers (Sense, Interpret, Decide, Orchestrate, Learn) work with interchangeable models, not hard-wired ones.
Effort and benefit
Yes, the flexible path costs more at the beginning. You build abstraction layers, run evaluations across multiple providers, maintain fallback paths, and own the governance. A pure “everything on one vendor” setup is faster to stand up and often cheaper to operate in the first months.
Over the medium and long term, the balance reverses. You keep negotiating power on price and limits. You can use the best model for each task instead of waiting on one provider’s roadmap. Outages, deprecations, or regulatory restrictions do not hit the entire system. Exit costs stay manageable because the company owns the context, logs, and rules.
The twin makes the comparison visible. When the flexible architecture outperforms the old path on the same workflows—faster, cheaper, lower risk—it supplies the evidence to retire the incumbent. The extra cost of modularity is recovered where the core would otherwise remain stuck in verification work, rework, and stalled change.
AI-native transformation needs this freedom of movement. Otherwise, you only optimize the dependency.